REPLWARE|Modern Data Stack Implementation

Your monthly report takes two days —
and the data can't go to the cloud.

REPLWARE builds modern data platforms on open source, deployed inside your own data center — no data leaving the firewall, no per-seat licensing. Stop renting your software stack. The technology becomes yours.

Clients include GiantPlus, CTBC and Kumon Author of the first Modern Data Stack book in Traditional Chinese

What we usually walk into

All the data exists. None of it adds up to a cross-system report you can trust.

For mid-sized enterprises the blocker is rarely "should we adopt AI". It is usually these four things, unresolved.

Every report is last week's number

Data sits across ERP, MES and departmental spreadsheets. A cross-system monthly report takes two days of manual VLOOKUP, and by the time it is out the numbers are a week old.

The data cannot leave the firewall

Customer lists, financials, process parameters — compliance or a parent company forbids the cloud. Most SaaS data tools fail at the first gate.

Licensing costs climb every year

Commercial BI and ETL tools are priced per seat. As adoption grows the renewal grows with it, and you have no credible alternative to negotiate with.

Nobody can maintain it once the consultant leaves

IT is two or three people. A vendor delivers a black box; every change means another statement of work, and the platform becomes one more legacy system nobody can maintain.

What REPLWARE does

Three things, in one engagement: build it, keep it on-premise, hand it over.

S1

Data Platform Implementation (Modern Data Stack)

Turn the two-day monthly report into a single click

We consolidate data from ERP, MES, CRM and departmental spreadsheets into one platform, with maintainable data models and automated orchestration — so every report has a single, traceable source of truth.

ClickHousedbtMetabaseKestraMeltano
S2

On-Premise Open Source Deployment

Data stays behind your firewall, with no per-seat licence

Everything runs in your own data center or private cloud, meeting data residency and compliance requirements. The stack is built on proven open source projects, so the platform belongs to you — no vendor lock-in, no subscription dependency.

S3

Engineer Enablement & Knowledge Transfer

Changing a report later takes no new statement of work

Our consultant and your assigned engineer develop together: the SQL, the data models and the architecture documents are produced jointly. At close, your team can extend and operate the platform on its own.

How we work

Four stages, about three months, with the acceptance criterion agreed up front.

Timeline, commitment and definition of done are settled in the first meeting — not discovered after the contract is signed.

01

Deep-dive conversation

We map your current systems, data flows and bottlenecks, and confirm whether our approach applies.

02

Proposal & roadmap

A tailored proposal defining the platform's boundaries, the technical stack, and a concrete roadmap with dates.

Output: proposal and schedule

03

Build & on-site work

One day per week on-site, building alongside your assigned engineer so the knowledge transfers as the platform goes up.

~3 months · 1 day/week on-site

04

Acceptance & handover

In the proposal stage we agree on one representative report or business rule. The engagement concludes when that logic runs end to end on the new platform; your team migrates the rest the same way.

Done = the agreed sample logic runs live

Before we start: what we need from you

  • One dedicated engineer, 1–2 days per week alongside our consultant. This is what makes knowledge transfer work, and it cannot be skipped.
  • Access to systems and data, including read access to source systems and the deployment environment.
  • A project budget in the seven-figure range in NT dollars. The exact figure depends on the number of data sources, the complexity of your existing systems and the scope, and is confirmed at the proposal stage.

Client results

GiantPlus: from 27 minutes to 10 seconds.

100x Machine report generation speed
3x Report development speed
3 months Time to build the platform

“Laurence helped us implement the Modern Data Stack, rapidly building out our data platform in just about three months. The results were transformative: report generation time was slashed from 27 minutes to under 10 seconds. Furthermore, our team's report development speed has tripled. Laurence's expertise delivered both performance and agility.”

Selected clients

GiantPlus Technology CTBC Bank XREX Inc. Kumon GMCSR Invistron
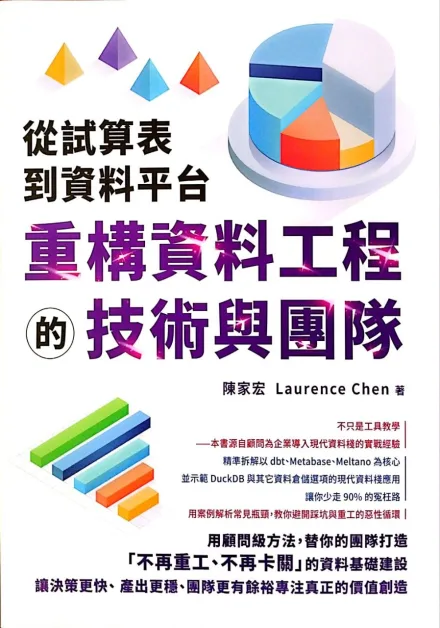
Cover of From Spreadsheets to Data Platforms

Published by REPLWARE

From Spreadsheets to Data Platforms

《從試算表到資料平台》— Building a data platform, and the data-driven future

The first systematic treatment of the Modern Data Stack published in Traditional Chinese, written by REPLWARE founder Laurence Chen. It covers the architectural thinking, the implementation practice, and the organisational resistance enterprises meet when adopting a data platform.

The book describes the method REPLWARE actually uses. Read it first, then decide whether you want us.

About us

REPLWARE (睿博資訊有限公司)

REPLWARE was founded in 2020. We build on-premise data platforms on open source technology for mid-to-large enterprises in Taiwan.

Our clients tend to share two traits. Their data cannot go to the cloud, for compliance or commercial sensitivity. And their IT team is small enough that a black-box system — where every change means another purchase order — is not viable. So we hand the architecture and the implementation method over to your engineers in full.

If you are evaluating a data platform, write to us. Let's talk first and see whether this is genuinely the right thing for you to be doing.